Why AI Sometimes Gives a Confident Answer Before It Has Enough Information
There is something oddly convincing about a wrong AI answer. It may be written in complete sentences. It may explain the subject step by step. It may even include specific names, dates or numbers. Nothing about the wording necessarily tells you that the answer is uncertain.Then you check the information and discover that something is missing—or simply wrong.
This is one of the more important limitations of modern artificial intelligence. A language model can produce an answer that sounds certain even when the available information does not justify that level of confidence. Researchers have repeatedly studied this problem under the broader area of hallucination and confidence calibration.
But why does this happen in the first place?
The answer has less to do with AI deliberately trying to mislead someone and more to do with how these systems generate language.
AI Is Designed to Produce an Answer, Not to Pause Like a Human Expert
When a person doesn't know something, there is usually a simple option:
"I don't know."
A language model can say those words too, but its underlying mechanism is different from human reasoning.
A language model generates text based on patterns learned during training. At each stage of generation, it selects likely continuations that fit the context. Producing a fluent answer is therefore not the same thing as proving that the answer is factually correct.
That distinction is easy to overlook because today's models are exceptionally good at producing natural language.
Research on language-model calibration has found that model confidence does not always correspond well with the probability that an answer is correct. In other words, a confident-sounding response cannot automatically be treated as evidence that the model is right.
A Missing Detail Can Change the Entire Answer
Consider a simple question:
"Who designed this building?"
If the user doesn't provide the building's name, location or photograph, there may not be enough information to identify it reliably.A cautious system should ask for clarification.
But language models can sometimes infer what the user might mean and continue with an answer anyway.This becomes especially risky when a question has several plausible interpretations.
Recent research into uncertainty in language models has specifically examined how interaction and clarification can help when a question is underspecified. The basic idea is straightforward: sometimes asking another question provides information that the model cannot safely infer from the original prompt.
That is why a useful AI assistant should not treat every incomplete question as an invitation to guess.
Fluency Can Hide Uncertainty
Humans often use speech patterns to judge confidence. Someone who hesitates, corrects themselves or says "I'm not completely sure" sounds uncertain.AI-generated text can behave differently.
A model can produce polished prose even when the underlying answer is unreliable. Research published in 2025 found that large language models can use an assertive language style while making false claims, describing this phenomenon as overconfident hallucination.
This creates a dangerous gap:
The confidence of the writing can be higher than the reliability of the information.
A beautifully written paragraph is still just a paragraph. Its tone does not verify its facts.
Why AI May Fill in the Missing Pieces
Suppose someone asks:
"What happened during the meeting between these two companies?"
But the question doesn't provide a date, location or source.There may be several events involving the same companies.
Instead of stopping, an AI system may generate a plausible continuation based on patterns associated with the question.This can produce an answer that feels reasonable because the individual pieces of the sentence are familiar.The problem is that familiarity and factual verification are not the same thing.
This is one reason researchers use the term "hallucination" for cases where language models generate information that isn't supported by the available evidence.
Being Good at Language Doesn't Mean Being a Perfect Fact Checker
This distinction is probably the most important one to understand.
A language model can be excellent at:
explaining complicated ideas,
rewriting text,
summarizing information,
recognizing patterns,
generating different styles of writing,
and connecting related concepts.
None of those abilities guarantees that every factual statement it produces is correct.
Research into language-model truthfulness has found that models can contain useful internal representations of factual information while still producing outputs that do not accurately express that information.
So there can be a difference between what a model has represented internally and what eventually appears in its answer.
That is one reason simply asking an AI to "be confident" is not a reliable way to improve accuracy.
Confidence and Accuracy Need to Be Calibrated
Researchers use the term "calibration" to describe whether confidence corresponds appropriately to correctness.
Imagine an AI gives 100 answers and labels 80 of them as highly confident.If only 50 of those answers are actually correct, the system's confidence is poorly calibrated.
Ideally, higher confidence should correspond to a higher likelihood of being correct.
This problem isn't new. A 2021 study examining language models found that their confidence estimates were not reliably calibrated to answer correctness and investigated methods for improving that relationship.
More recent research continues to show that calibration remains an active challenge. A 2024 EMNLP study described confidence calibration as important for factual reliability and noted that simply filtering out low-confidence responses can also reduce useful correct answers. So the solution isn't as simple as telling an AI to "only answer when you're 100% sure."
Sometimes the Model Can Be Right for the Wrong Reason
There is another complication.An AI may produce the correct answer without having a dependable reason for doing so.It might recognize a familiar pattern that happens to lead to the right result.Change the wording slightly, however, and the answer could change.
A 2025 study described a phenomenon in which models that could answer a question correctly were sometimes pushed into producing a confident hallucination by seemingly small changes to the prompt. The researchers called this phenomenon "CHOKE", or Certain Hallucinations Overriding Known Evidence.
This illustrates why a correct answer from an AI is not automatically proof that the system understood the question in the same way a human expert would.
More Information Can Help
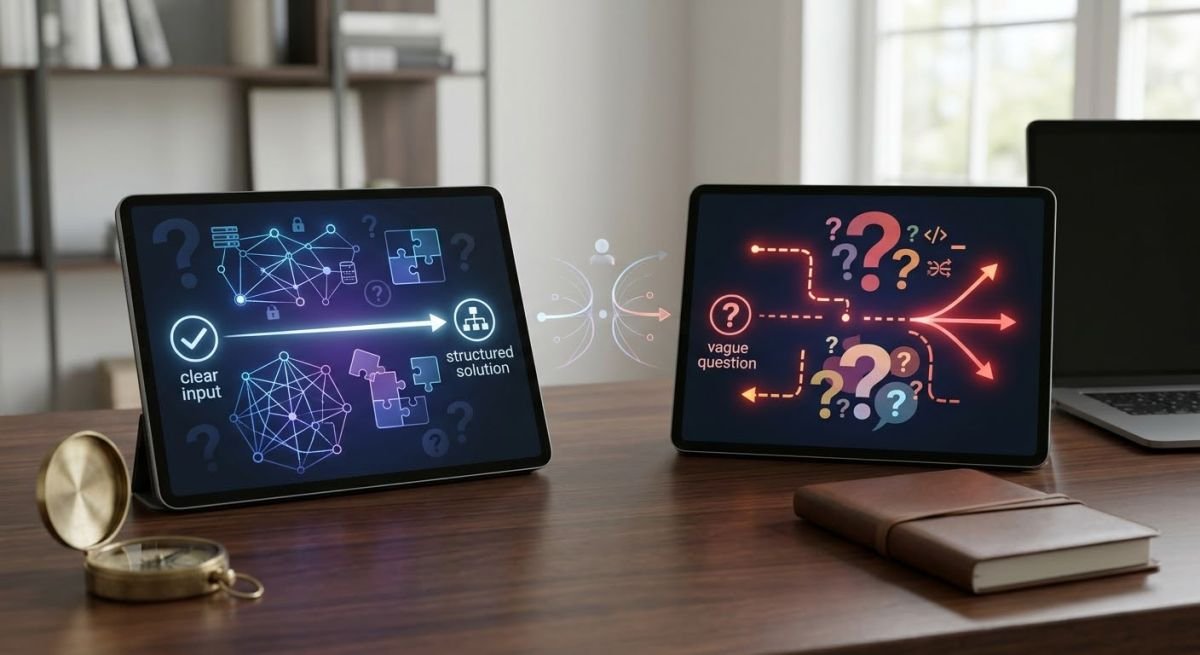
One practical way to reduce this problem is to give the model better information.
Instead of asking:
"Is this contract safe?"
a user could provide the relevant section of the contract and ask:
What clauses in this section could create financial obligations?
The second question gives the system a much clearer basis for its response.
The same principle applies to research, technical questions and document analysis.
Useful context can include:
the exact document,
dates,
names,
relevant measurements,
the source of the information,
screenshots,
or the specific problem being investigated.
The more important the decision, the more important it becomes to distinguish between information supplied by the user and information the model is merely inferring.
Asking a Follow-Up Question Can Be a Sign of Better AI
People sometimes think an AI is less capable when it responds:
"Could you clarify what you mean?"
In reality, that can be the more responsible response.If several interpretations are possible, asking for the missing information reduces the chance of confidently choosing the wrong one.
Research published in 2026 has explored interactive approaches to uncertainty calibration, finding that clarification and interaction can help models handle underspecified inputs more reliably.
A good AI system therefore shouldn't measure success only by how often it produces an immediate answer.Sometimes the best response is a question.
What Users Can Do to Avoid Confidently Wrong Answers
You don't need to treat every AI response as useless.You simply need to understand where verification matters.
For ordinary brainstorming or rewriting, a minor factual mistake may not matter much.
For medical, legal, financial, academic or technical decisions, it can matter considerably.
A few habits can help:
Ask for sources when factual accuracy matters.
Give the model the relevant context instead of leaving important details unstated.
Ask it to identify uncertainty rather than forcing a definite answer.
Check names, dates, statistics and quotations independently.
Be especially cautious when the answer contains unusually specific information that you did not provide.And if the information affects an important decision, verify it against a trustworthy primary or professional source.
AI Is Getting Better at Expressing Uncertainty, but the Problem Isn't Solved
Researchers are actively working on ways to make AI systems better at recognizing and communicating uncertainty.
Some approaches attempt to calibrate the model's confidence. Others examine its internal representations, use additional verification, or encourage the system to abstain when it lacks sufficient evidence.
There is progress, but no method makes every AI response automatically trustworthy.
Recent research still finds overconfidence in advanced reasoning models, showing that even systems capable of sophisticated multi-step reasoning can produce confident incorrect answers.
That means users should not confuse improved reasoning ability with guaranteed factual reliability.
The Real Problem Is the Gap Between Sounding Right and Being Right
Perhaps the easiest way to understand AI confidence is to separate two different things.
"How convincing an answer sounds" is one question.
"How well the answer is supported by evidence" is another.
Those two qualities can overlap, but they are not identical.
An AI can write a convincing explanation from incomplete information. It can choose a plausible interpretation when several exist. It can produce a specific detail that was never established. And it can express the result in a calm, authoritative tone.
That doesn't necessarily mean the system is intentionally deceiving you.It means the language it produces should not be treated as its own proof.
The Bottom Line
AI sometimes gives a confident answer before it has enough information because fluent language generation and factual certainty are different problems.
A model can produce coherent, persuasive text without having enough evidence to support every statement. Research into language-model calibration and hallucination has repeatedly demonstrated that confidence expressed in an answer does not always track correctness.The safest way to use AI is therefore not to judge an answer by how confident it sounds.
Give it the relevant information. Allow it to ask questions. Look for uncertainty when the evidence is incomplete. And when the consequences matter, verify the important claims independently.
The most convincing AI answer is not necessarily the most reliable one. What matters is whether the confidence behind the words matches the evidence supporting them.